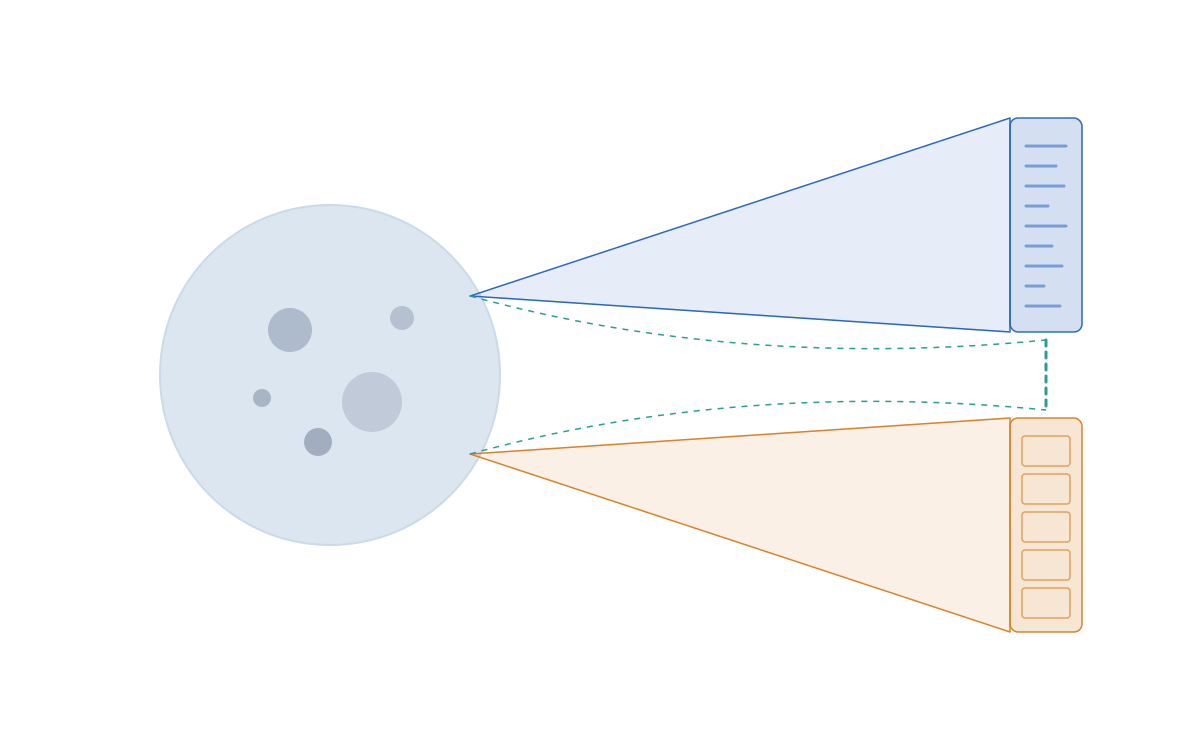
Video Models Give Language Models a Second Error Channel
Two principles explain what video generation can contribute to machine intelligence: a model's knowledge is capped by its training target, and a query is informative only if its conditioning carries no information about the outcome. We develop both, show with two generations where text-to-video products break the second, and argue that controllability and prediction are dual.